
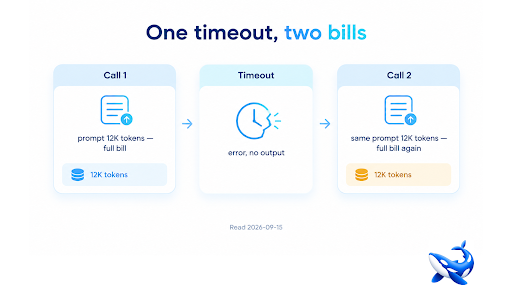
A failed LLM API call is not free. The provider already processed the request, so the tokens were metered before the error reached you, and the retry that follows processes the same tokens a second time. On long prompts that means one timeout costs two full bills for one finished result — and the same arithmetic runs through every gateway, because the token metering happens upstream of the route. OrcaRouter keeps the rate itself at pass-through so the failure cost is visible in the number you are quoted, and the cheapest llm api provider comparison only works if the retry cost is on the table too.
All prices and latency figures read 2026-09-15.
A timeout is a double bill, not a missed call
Billing for an LLM API is consumption-based: the moment the provider accepts the request, the input tokens are counted, and they are counted again on a retry that resubmits the same text. A request that times out mid-stream, errors at the tail, or gets interrupted by a deploy has already consumed its input tokens, and the fallback re-runs them in full. Two attempts at one answer means the input is billed twice and the output once — assuming the second attempt finished.
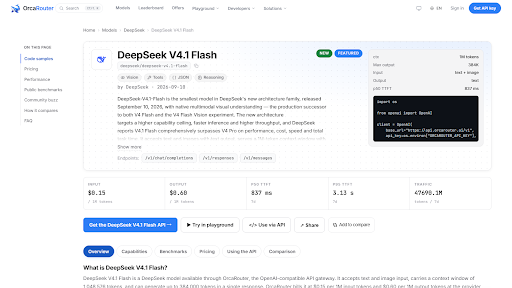
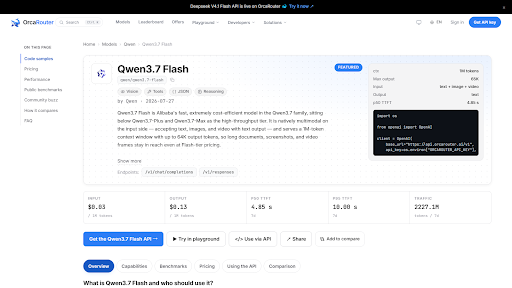
The unit of that loss is set by how much text each call carries. A simple call is a rounding error; a long-context call is not. Take the cheap tier of the catalog — 190 English model pages today, more than 200 models behind one API by its own headline — and a 12,000-token prompt is unremarkable. On the lowest rate in the catalog it is trivial; on a mid-tier rate the double bill stops being noise:
| Model | Input /1M | Output /1M | 12K prompt, twice |
| Qwen3.7 Flash | $0.03 | $0.13 | $0.0007 |
| GLM 5.3 Flash | $0.07 | $0.25 | $0.0017 |
| DeepSeek V4.1 Flash | $0.15 | $0.60 | $0.0036 |
| GPT-5.4 Nano | $0.20 | $1.25 | $0.0048 |
| Gemini 3.1 Flash Lite | $0.25 | $1.50 | $0.0060 |
One retried call is cents. A hundred thousand retried calls a month is hundreds of dollars, delivered by a code path nobody labelled as spending.
Where the real retry cost lives
The per-call figure understates the problem, because the expensive retry is the one on the long request. Timeouts correlate with long prompts and with peak load — the jobs that take the longest to answer are exactly the ones most likely to hit your client-side limit — so the failure rate and the token size multiply in the same direction. A retry storm during a spike is a bill that grows quadratically: more concurrent long requests, more timeouts, more full re-submissions, all at the moment of peak volume.
The industry-default response is a retry loop, and a retry loop with exponential backoff is the standard way to keep a server up — but it is also the most expensive way to spend tokens, because it re-sends the entire payload on every attempt. The cheaper pattern is resumable work: chunk long jobs, checkpoint progress, and retry only the unfinished piece instead of the whole request. On a task that fails at 90%, that is the difference between re-billing 100% of the tokens and re-billing 10%.
The second lever is the layer. Most AI gateways add a margin on every token they carry — commonly in the 5% to 20% range of your token spend, a characterization from OrcaRouter’s own pricing page. That margin is charged on the failed call too, because the failed call metered tokens. A gateway that bills per attempt on top of the provider’s rate makes a retry storm proportionally more expensive than the provider alone, and none of that extra cost appears as a line item. The pass-through position — a fee column that reads $0.00, with the product funded by optional Team and Enterprise subscriptions rather than by a cut of spend — means the failure cost is the provider’s actual rate, and no more.
The failure-rate audit
The practical question is how much of the bill is retries, and the answer is measurable in logs. For a month of traffic, three numbers close the loop:
- Input tokens on attempts that did not produce a kept result. Those are the wasted input.
- Input tokens on retries of those attempts. Those are the double-billed input.
- Total output tokens that were discarded. Those are the wasted output.
The ratio of sum to useful output is the real efficiency of the integration, and it is the number that decides whether the bill is tight. Most teams have all three in their logs; almost none have computed the total. When they do, the usual discovery is that retries and discarded work are worth several times more than any difference between models in the cheap tier — the entire $0.03 to $0.25 input range is smaller than one retry pattern on a long job.
Failover without double-paying
Failover — sending a request to a second provider when the first fails — is the same problem one layer up, and the retry pattern decides its cost. Blind re-submission to the fallback bills the input twice at two providers. Resumable, chunked work with checkpointing bills only the unfinished tail once. The rule that keeps failover cheap is identical to the rule that keeps retries cheap: never resend work that already succeeded.
A subtle point follows from the layer. If the primary route is pass-through and the fallback route carries a hidden margin, then the failover that was supposed to protect reliability is simultaneously the more expensive path — and its price difference is invisible, because it is inside the quoted rate. The cheapest setup for reliability is the same setup as for cost: a pass-through layer on both paths, and resumable retries on both, so the failure cost is bounded by the provider rate rather than multiplied by it.
The failure budget
A timeout is not a miss; it is a double bill, and it is controllable. Count the attempts that do not produce kept output, make retries resumable so only the unfinished piece re-bills, and keep the layer off both the primary and the fallback path so no attempt carries a hidden margin. Done in that order, the failure cost drops to a rounding error — which is what “cheapest provider” should mean: not the lowest quoted number, but the number that stays low when things go wrong. And when you check a provider, the one-number test is the fee column: if it does not read $0.00, you cannot even see the failure cost you are paying.
Sourcing note: Model rates and median time-to-first-token figures are OrcaRouter’s own catalog and production telemetry, read 2026-09-15; latency is a 7-day rolling window reflecting one platform’s traffic mix, regions and live provider load, not a controlled benchmark, and one entry reports a 10.00 s reporting ceiling rather than a measured value. The token-consumption billing model described is standard practice for LLM API providers. The 5% to 20% markup range describes common gateway practice as characterised on OrcaRouter’s own pricing page, not an independent survey. The retry-pattern and failover guidance is our own engineering recommendation based on how token billing works.